Theo Lehmann · 18 October 2026
Examining Resilience Features in Note Platforms When Facing Unexpected Service Disruptions
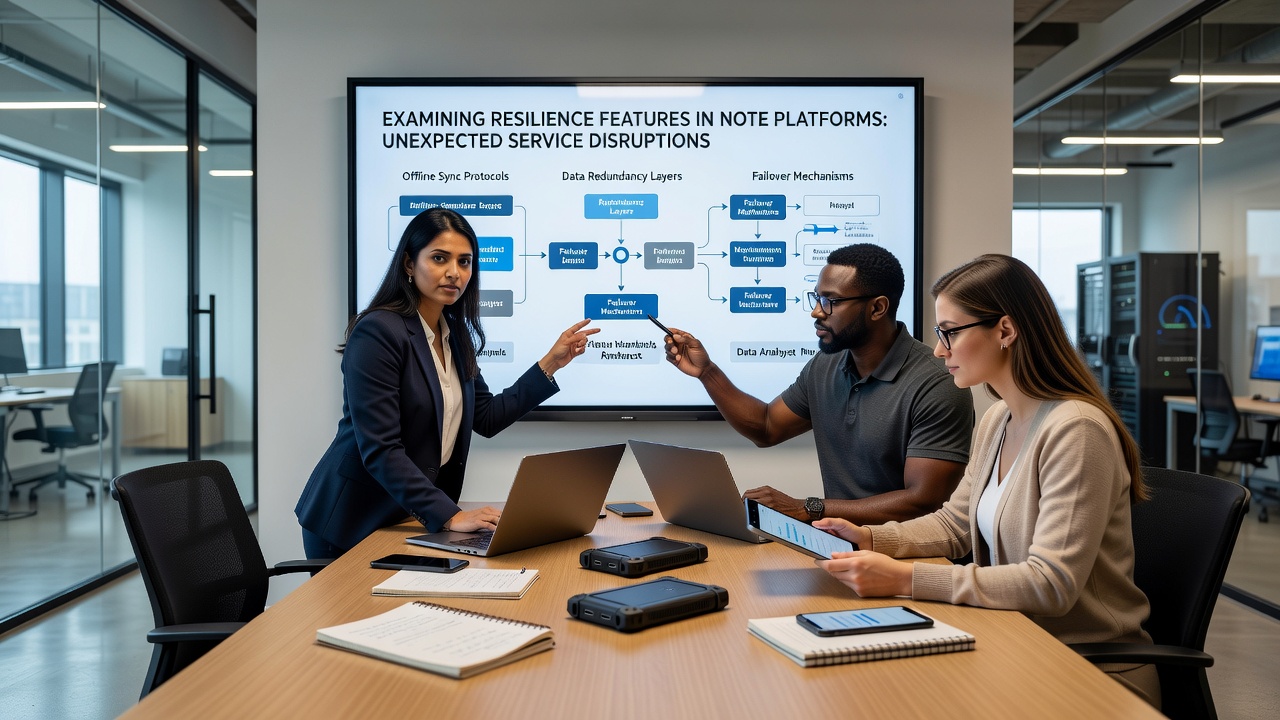
Digital note platforms store critical information for millions of users worldwide, and service disruptions can stem from network failures, data center outages, or software bugs that suddenly limit access. Researchers have examined how these platforms maintain functionality when core services falter, focusing on built-in mechanisms that prevent total data loss or prolonged downtime. Data from industry analyses show that platforms with strong resilience architectures recover faster than those relying solely on single-region hosting.
Unexpected events often hit during peak usage periods, forcing systems to reroute traffic or activate secondary servers. Observers note that effective designs incorporate automatic failover protocols, which shift operations to backup infrastructure within seconds of detecting an issue. This approach keeps user sessions active even while primary nodes undergo repairs, and studies from cloud infrastructure reports confirm that such redundancy reduces average recovery time by measurable margins.
Core Mechanisms That Support Continuity
Resilience in note platforms rests on several technical layers working together. Multi-region data replication copies notes across geographically separated facilities so that an outage in one location does not erase access elsewhere. Local caching allows users to continue editing on their devices while the platform reconnects, and conflict-resolution algorithms merge changes once connectivity returns. According to findings published by the National Institute of Standards and Technology, these combined techniques help organizations maintain operational continuity during infrastructure stress events.
Encryption remains active throughout these processes, protecting data both in transit and at rest on backup servers. Platforms also maintain detailed logging that records every sync attempt, enabling post-incident reviews to identify weak points. Those who analyze outage reports find that detailed telemetry speeds up root-cause identification and helps teams refine their response playbooks over successive incidents.
Real-World Responses to Service Interruptions
One documented case involved a major note service that experienced a multi-hour regional failure in early 2025, yet most users retained read-only access through cached versions stored on their devices. Engineers activated cross-region failover and restored full synchronization within ninety minutes, demonstrating how pre-positioned replicas limit user impact. Similar patterns appear in European service logs examined by the European Union Agency for Cybersecurity, where platforms using distributed storage recovered more quickly than centralized alternatives.
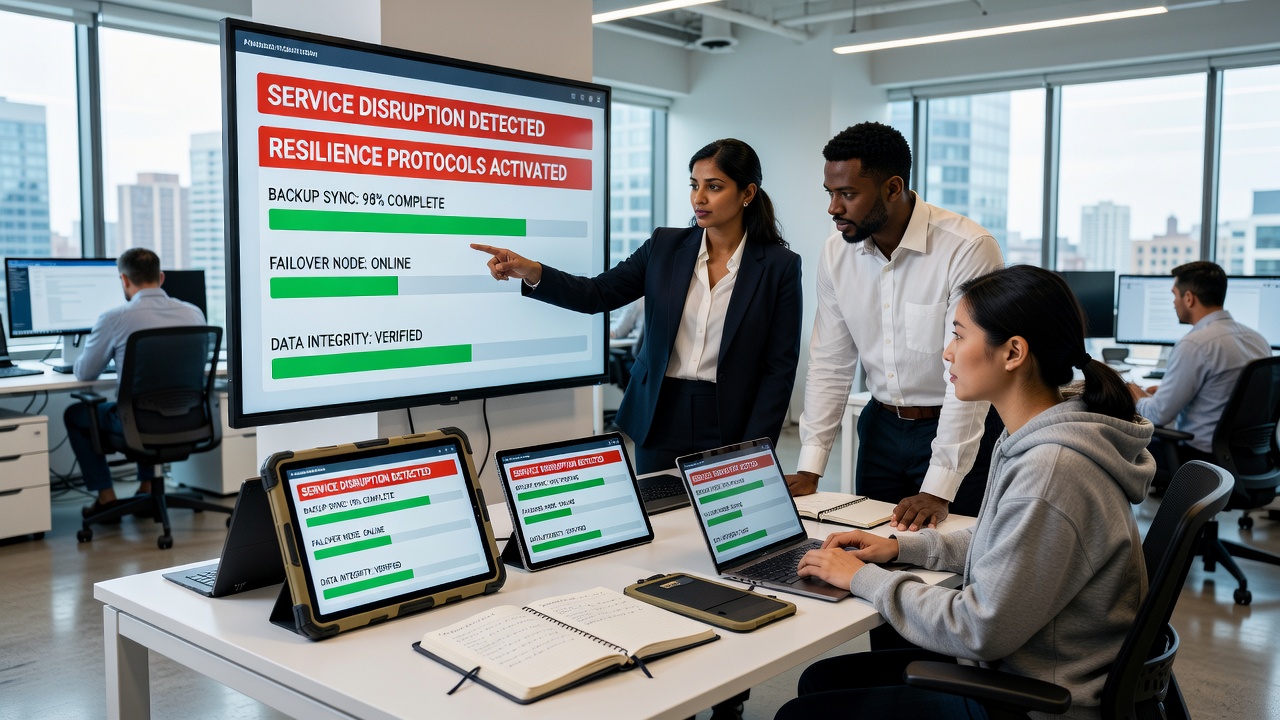
October 2026 brought additional attention to these capabilities when several providers upgraded their architectures ahead of anticipated traffic spikes from academic calendars. The upgrades included expanded edge caching and improved heartbeat monitoring between nodes, allowing faster detection of latency spikes. Figures from post-upgrade monitoring indicate that platforms with these enhancements handled brief network flaps without triggering user-visible errors.
Evaluation Criteria Used by Analysts
Analysts assess resilience through metrics such as recovery point objective, which measures how much data might be lost during an outage, and recovery time objective, which tracks how quickly services resume. Platforms that publish these figures allow users to compare offerings directly. Research from academic teams at institutions like the University of Toronto highlights that transparent reporting correlates with higher user retention after incidents because it builds confidence in the platform's ability to protect information.
Additional safeguards include offline-first design patterns that let users queue changes locally and versioned backups that permit rollback to earlier states if corruption occurs during recovery. These features operate continuously in the background, and their effectiveness becomes visible only when primary systems encounter trouble.
Conclusion
Resilience features in note platforms combine replication, caching, and monitoring to keep information accessible during unexpected disruptions. Data collected across multiple providers demonstrate that platforms investing in distributed infrastructure experience shorter and less severe outages. Continued refinement of these mechanisms supports reliable access for users who depend on note platforms for daily work and study.